In particular I like very much Rotem’s definition of the four principles of Change Driven Design:
1. Areas of change should be contained.
2. Things that are more likely to change should be easier to change.
3. Things that are less likely to change should not depend on things that are likely to change.
4. Change should entail extending the system rather than refactoring.
END quote
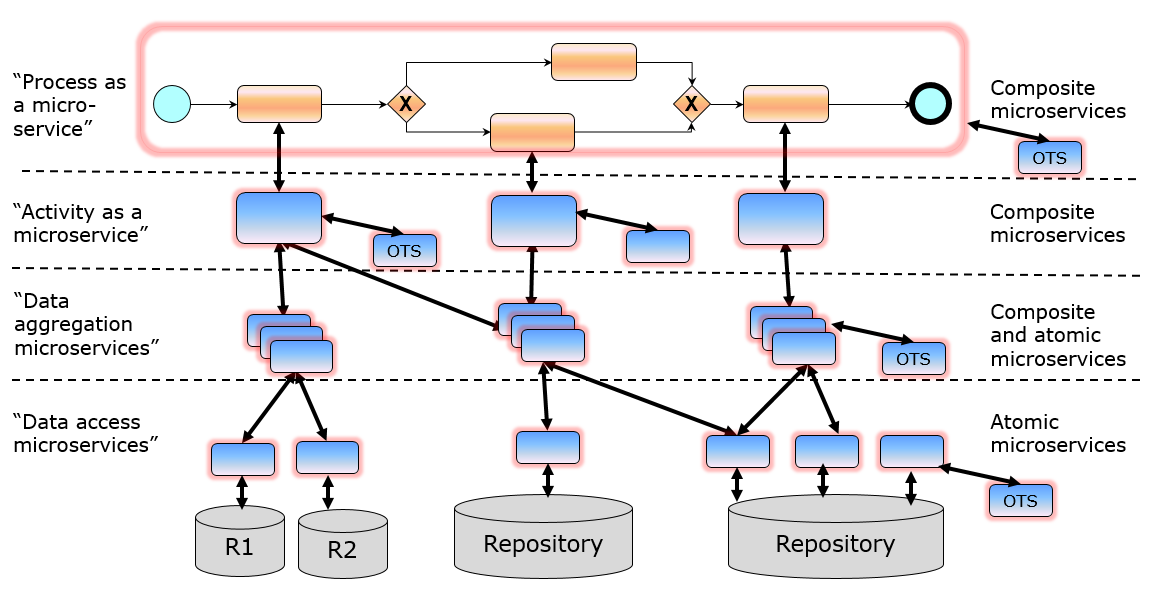
RE item 2: Many types of changes must be anticipated in the architecture and thus they are easy to do. Other changes must be possible. For example, [REF1] states that business-process-centric solutions have several types of artefacts: event, business-process, rule, role, activity, data, document, audit trail, and KPI. Their changes are anticipated and these artefacts are structured as shown below.
All artefacts are available as microservices – see below (only 4 lower layers are shown).
Techniques for composition of microservices: DSL (BPMN, DMN), interpretive general languages (Groovy), compiled generic languages (Java). Off-The-Shelf (OTS) microservices can be used as necessary, e.g. business process engine for BPMN.
RE item 4: Technical changes should be fused with business changes in accordance with the PDCA cycle.
[Plan] measure how the work is done,
[Plan] observe the business environment,
[Plan] decide in what areas the solution should advance,
[Do] implement the decisions taken,
[Check] validate the effect of those decisions, and
[Act] refactor some microservices to adopt internally the improvements.
RE “In short, the application architectural style known as microservice architecture (MSA), is unlikely to be an appropriate choice for the early stages of an application.”
On the contrary, at the early stages of solution elaboration as a functional prototype, a high rate of changes is mandatory thus microservices-based solutions offer a huge gain in development time.
Yes and [REF1] offers slicing and dicing out-of-the-box – vertical separation by business processes and horizontal layers as shown in illustrated above.
Many articles about microservices mentioned “process”. I believe they mean “computing process” (e.g. an instance of JVM) which should not be confused with “business process”.
2.2 Orchestration
Another confusing term is “orchestration”. In some articles, it means “container orchestration layer” which allows one to specify how the microservices are handled in fault tolerant and in scaling up and scaling down.
O’Reilly book “Migrating to Cloud-Native Application Architectures” (http://pivotal.io/platform-as-a-service/migrating-to-cloud-native-application-architectures-ebook ) says “The ESB becomes the owner of all routing, transformation, policy, security, and other decisions governing the interaction between services. We call this orchestration, analogous to the conductor who determines the course of the music performed by an orchestra during its performance. ESBs and orchestration make for very simple and pleasing architecture diagrams, but their simplicity is deceiving. Often hiding within the ESB is a tangled web of complexity.” I think, this is a wrong analogy. The conductor delivers only one symphony at a time. ESB delivers many symphonies at the same time. Not surprising that it such “centralised orchestration” is difficult.
In other articles, it means one of two BPMN ways to compose business processes – orchestration as a strong coordination and choreography as weak coordination. This orchestration is a domain bounded because it is carried out in the scope of a particular business process.
2.3 Microservice or Autonomous Component (AC)
Microservice is a unit of functionality which is
explicitly-defined for a potential consumer how to use it (yes, there is a formal contract)
universally-accessible for its consumers via standard protocols (not just REST)
In addition, microservices are:
design-interdependent (design-time dependency in accordance with the overall design of a software-intensive solution)
operationally-independent (i.e. unavailability of a particular microservice may be compensated without total unavailability of the whole solution)
contractually-dependent (run-time dependency in accordance with the formal contract)
“Unit-of-functionality” means Single Responsibility Principle (SRP). Thus a microservice with a greater and single responsibility may be composed from microservices with lesser and single responsibilities.
Obviously, microservices is that old-known services should be.
2.4 Microservice architecture
Microservice architecture (as well as SOA) is an architectural style for constructing software-intensive solutions from a set of universally interconnected and interdependent services/microservice.
The artificial separation “SOA is for integration between applications” and “microservice architecture is for applications” has no sense anymore because the integration between two “microserviced” applications is the same as integration between microservices within each of “microserviced” application.
3 Review of some posts
Several articles about (mainly negative) about applicability of microservices.
A very good article showing that the current “microservice architecture” is a bit weak to be considered as a real architecture (thus provide a solid based for industrial delivery of software-intensive solutions).
Of course, it is very difficult to maintain an application with a rather weak architecture. Just a few points.
Structure is necessary instead of a flat microservice-to-microservice topology. It helps to testing, integrity and reducing the level of complexity.
Strongly and statically typed language is preferable for interfaces, i.e. between microservices. Weak and dynamic type language is OK within microservices.
Monitoring and testing may merge: testing becomes on-going, and monitoring becomes more functional.
Real architecture must enable quick deployments of new versions of solutions.
RE “So my primary guideline would be don't even consider microservices unless you have a system that's too complex to manage as a monolith. The majority of software systems should be built as a single monolithic application. Do pay attention to good modularity within that monolith, but don't try to separate it into separate services.”
This is yet another confirmation that the current “microservice architecture” is a bit weak to be considered as a real architecture. There are two viewpoints: a) external service provider viewpoint who is engaged for a well-defined scope and b) enterprise-wide viewpoint for considering software-intensive systems within an enterprise TOGETHER. The different between them is like seeing the trees or the forest.
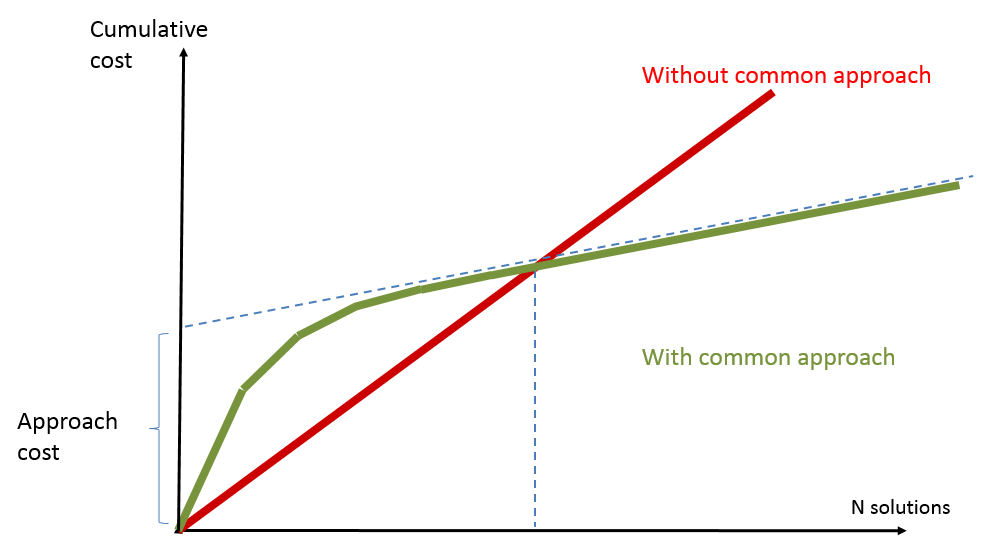
Obviously, some initial efforts are necessary to establish microservice-centric environment and practices. These efforts will pay-off after several applications.
In addition, each subsequent solution is cheaper because it reuses the same tools, the same services, the same architecture.
This cloud-friendly application architecture opens the way to synergy between #BPM, #SOA, #cloud, #microservices, #IoT, #digital and #security.
2 Clarification of some terminology
2.1 Process
Many articles about microservices mentioned “process”. I believe they mean “computing process” (e.g. an instance of JVM) which should not be confused with “business process”.
O’Reilly book “Migrating to Cloud-Native Application Architectures” http://pivotal.io/platform-as-a-service/migrating-to-cloud-native-application-architectures-ebook says “The ESB becomes the owner of all routing, transformation, policy, security, and other decisions governing the interaction between services. We call this orchestration, analogous to the conductor who determines the course of the music performed by an orchestra during its performance. ESBs and orchestration make for very simple and pleasing architecture diagrams, but their simplicity is deceiving. Often hiding within the ESB is a tangled web of complexity.” I think, this is a wrong analogy. The conductor delivers only one symphony at a time. ESB delivers many symphonies at the same time. Not surprising that it such “centralised orchestration” is difficult.
In other articles, it means one of two BPMN ways to compose business processes – orchestration as a strong coordination and choreography as weak coordination. This orchestration is a domain bounded because it is carried out in the scope of a particular business process.
Microservices communicate with each other through language and platform-agnostic application programming interfaces (APIs). These APIs are typically exposed as Rest endpoints or can be invoked via lightweight messaging protocols such as RabbitMQ. They are loosely coupled with each other avoiding synchronous and blocking-calls whenever possible.”
The first of these two paragraphs says that each microservice is “independent” from other microservices and the second paragraph says “microservices communicate with each other” thus there is some dependency.
Certainly, microservices are interdependent by design and operationally-independent. It seems that microservices may refer to each other indirectly via a “naming service” (some kind of URI to URL mapper or like in CORBA). Therefore, a microservice may employ other microservices to complete its work. In extreme, a microservice may be an assembly of microservices. Article http://microxchg.io/2015/slides/02_01_DomainServiceAggregators.pdf provides an example of data aggregation with a business domain.
Yes, size in LOC does not matter. There is only one limit – SRP. Interesting, that no limitations on “size” of this single responsibility. Thus a microservice with a greater and single responsibility may be assembled from microservices with lesser and single responsibilities.
From https://genehughson.wordpress.com/2015/02/06/wait-did-i-just-say-knuth-was-wrong/ “In the comments, it was suggested that granularity was irrelevant as multiple granular microservices could be composed to form a coarser-grained microservice that would provide a more appropriate level of abstraction. My response was that while this is theoretically true, aggregating service calls in that manner risks issues due to network latency.”
In addition for my comments to that blogpost, I would like to add that designing microservices as distributed autonomous components (each with own computing process) is forcing to consider (up-front and not as refactoring) a proper error-recovery which is much more difficult than the error-handling when components are in the same computing process.
In general, a business capability is a cohesive set of processes (or cluster of processes in accordance with http://improving-bpm-systems.blogspot.ch/2014/03/enterprise-as-system-of-processes.html ). Those processes are implemented as assemblies of microservices. Some of those microservices are unique for a particular process and for a particular cluster; others are shared between clusters.
From https://www.voxxed.com/blog/2015/01/good-microservices-architectures-death-enterprise-service-bus-part-one/ “Microservices and their granularity are ideal for the development and maintenance of the service. But that does push complexity more towards the app itself. A complexity that those apps cannot manage as they are often executed on platform with constrained resources (battery, network, CPU). Combining services in a higher level logic to serve the purpose of apps or business processes proves to be faster to develop and easier to maintain.”
Yes, assembling of microservices is the way to reduce complexity.
If application as a unit of deployment (even decomposed into a few tiers) is no more the physical boundary then boundaries becomes logical and they are coming from the business – business functions, business services and business capabilities. Note they are actually just different viewpoints – see “Common understanding of #bizarch (business architecture) and #BPM” http://improving-bpm-systems.blogspot.ch/2015/01/common-understanding-of-bizarch.html . Less IT applications and more business-process-centric solutions.
From http://nealford.com/memeagora/2015/03/30/architecture_is_abstract_until_operationalized.html “Continuous Delivery and the DevOps movement illustrated the pitfalls of ignoring the effort required to implement an architecture and keep it current. There is nothing wrong with modeling architecture and capturing those efforts, but the implementation is only the first step. Architecture is abstract until operationalized. In other words, you can’t really judge the long-term viability of any architecture until you’ve not only implemented it but also upgraded it. And perhaps even enabled it to withstand unusual occurrences.”
Correct, but slightly simplified observations – actually, 3 (three) major upgrades are necessary to demonstrate that architecture is good. Rationale: it is recommend leaving a solution team before the 3th major upgrade of this solution.
From http://www.infoq.com/articles/service-oriented-architecture-and-legacy-systems “Integration suites offer a complete stack that not only gives ESB capabilities but also more business-specific tools such as BPM (business process management), business activity monitoring, master data management, and a repository.”
As microservices become place-independent, it is necessary to have a good “naming service” (as we had in CORBA) to allow mapping of microservice’s URI to new URL. Such “naming services” is also known as discovery services.
At present, there is no synergy between microservices and API as illustrated by the following quotes:
From http://sdtimes.com/digging-into-microservices/ “The fundamental difference between microservices and APIs is that microservices are used to build applications, whereas APIs are used to integrate applications...”
From http://cloudramblings.me/2015/03/20/microservices-martin-fowler-netscape-componentized-composable-platforms-and-soa-service-oriented-architecture/ “Part of the problem with API management and micro-services or with the mediation / message broker middleware technologies is that these can impose a software layer that is burdensome on the micro-services architecture... Let us say an approach to implementing micro-services would be to put them into a traditional API Management service as offered by a number of vendors. There would indeed be an overhead introduced because the API Layers impose a stiff penalty of authentication, authorization, then load balancing before a message can be delivered. What is needed is a lightweight version of API Management for some trusted services behind a firewall that are low risk and high performance.”
From http://devops.com/blogs/containers-designed-antiquated-application-architecture/ “Cloud-scale applications by nature are stateless with any application state being managed by cache or database services. The compute unit of measure is the process not the CPU, which enables greater scalability. .... They scale across network architectures easily allowing businesses to run in private data centers and leverage cloud for excess capacity when needed.”
From http://12factor.net/backing-services “Twelve-factor processes are stateless and share-nothing. Any data that needs to persist must be stored in a stateful backing service, typically a database.” and “Treat backing services as attached resources”.
one persistency service (or backing service) for the state of the whole solution (even distributed solution)
predefined state which is created by embedding state into an individual containerized copy of the microservice (but the run-time knowledge about the context is mandatory)
idempotency
6.2 Performance
Potential techniques for performance improvement (primarily the network latency):
easy moving an individual containerized copy of the microservice between nodes (thus moving a microservice close to its consumer upto his/her mobile device)
on-demand creating an individual containerized copy of the microservice (but the run-time knowledge about the context is mandatory)
creating an individual containerized copy of the microservice for a particular consumer to diminish the security overhead (but the run-time knowledge about the context is mandatory)
6.3 Lightweight security
predefined state which is created by embedding security keys into an individual containerized copy of the microservice (but the run-time knowledge about the context is mandatory) thus achieving self-containment of PEPs
Let us look at the post “Architecting application architecture #apparch (inspired by #microservices)” http://improving-bpm-systems.blogspot.ch/2014/12/architecting-application-architecture.html and extend the described in it architecture to being cloud-friendly. In that blogpost, I introduced Autonomous Component (AC) with a note that at present, it is not possible to claim that ACs are microservices or services.
This architecture implements business solutions (instead of IT applications because the boundaries of IT applications are not relevant any more) as a coordinated collection of autonomous components. Each AC is a unit of functionality (as SRP) which can be executed in its own computing process (thus a unit of deployment which can be deployed in a separate host somewhere). An AC may be an assembly of several ACs. In general, ACs are structurally interdependent, behaviorally (or operationally) independent and contractually dependent.
Below, several typical ACs are described from the “being cloud-friendly” viewpoint through the following characteristics:
Contracting ACs: Use of some resource-access ACs and short-running ACs.
Example: Web-client or Fat-client for a document management system.
Note: Operation are usually short-running human and short-running automated ones.
Functional role-based portal (FRBP) AC to select a function and execute it with some data/documents as a user-facing AC. It provides two types of operations: 1) static list of functions what this role may do and 2) dynamic list of activities what this role has to do. A function is a set of activities.
Note: There are two types of operations: 1An operation may be short-running human, short-running automated and long-running one. The latter is a coordination of short-running ones and other long-running ones.
Human operation (HO) AC to interact with a human.
Cloud-friendly: stateless or stateful, multiple-place-independent, individual-instantiation.
Security techniques: RBAC, embedded.
Contracting ACs: May use some resource-access, resource-assembly-access and utility ACs.
Example: Interactive form.
Note: The state is kept in a solution-state persistence backing service.
Note: Human operation AC may be short-running and long-running.
Automated operation (AO) AC to transform some resources and/or solution-state data.
The cloud-friendly application architecture is demonstrated on video below to show how various ACs implement a typical process-centric solution (this video is inspired by http://improving-bpm-systems.blogspot.ch/2014/12/bpm-for-soaesbapi-and-cloud-paas-and.html ). Obvious, presented scenario may handle several process-centric solutions and several copies of the same solution (a copy per user) simultaneously.
The scenario has the following stages:
a) The functional-role-based-portal AC offers to a user some functions to initiate (as a static list). Each of functions is an explicit-coordination-operation AC which comprises several human-operation ACs and automated-operation ACs. Human-operations ACs are to be executed by users and they are dynamically listed for each users.
b) All explicit-coordination-operation ACs are implemented as DSL-script. The DSL-manager AC provides a list of functions which are offered for users. The DSL-processor AC provides a list of activities which have to be executed by some users.
c) A user executes a function which is implemented as a DSL-script; the DSL-manager AC instantiates an individual copy of this explicit-coordination-operation AC via the DSL-processor AC. (Covered by markers 1-3.)
d) The first of two operations within this explicit-coordination-operation AC is the automated-operation AC which uses several other ACs; the explicit-coordination-operation AC instantiates an individual copy of this automated-operation AC and individual copies of two of ACs used by it (“Utility” and “Resource assembly access”). Then the automated-operation AC is executed (Covered by markers 4-6.)
e) The second of two operations within this explicit-coordination-operation AC is the human-operation AC; the explicit-coordination-operation AC instantiates an individual copy of this human-operation AC and an individual copy of the other AC used by it. (Covered by marker 7).
f) The human operation AC must be completed by a user and it informs the explicit-coordination-operation AC. (Covered by markers 8 and 9).
g) The explicit-coordination-operation AC terminates.
and its static view
9 Conclusion
The cloud-friendly application architecture follows the business domain boundaries, processes, entities, documents, roles and rules.
The cloud-friendly application architecture reduces complexity by adding a structure among ACs:
long-running functions (actually, business processes)
short-running operations (actually activities or routines)
assembly of resources (actually, business entities or business objects)
resource (actually data and documents)
The cloud-friendly application architecture reinforces the information security by dynamics security for resources and embedded security for ACs
In the cloud-friendly application architecture the majority of ACs are cloud-friendly thus solutions based on this architecture are scalable.
The cloud-friendly application architecture covers majority of cross-cutting concerns : event handling, error recovery, persistence (state management), concurrency, security, interactions, distributed transactions, logging, monitoring and testing.
From the EA viewpoint, the topic of this discussion is the following:
There are two essential enterprise-wide artefacts “talented staff member” and “processes”.
Are there some relationships between these artefacts? It seems yes.
Are these relationships strong? i.e. a small change in one artefact may strong affect to another artefact? It seems yes.
So, how to achieve synergy between these artefacts? Let us allow talented staff members develop processes which simplify and amplify their work for the best of an enterprise.
Part of enterprise architecture is about establishing practices (processes and decisions) to govern (or to steer) some domains of enterprise activities. This blogpost provides a generic approach to setup domain governance.
1 Generic approach
Domain governance covers the entire life-cycle of the domain primary-artefacts.
Decompose the whole life-cycle into phases (or stages).
Each phase comprises several primary-artefacts, rules, activities and processes.
Responsibilities to own these primary-artefacts, rules and processes must be assigned to somebody.
Responsibilities to perform these processes and activities must be assigned to somebody.
All these responsibilities are grouped into several roles (under some considerations including “separation of duties”).
Domain stakeholders are assigned to these roles.
Various documents to support primary-artefacts are identified and their life-cycles are considered as well (roles to write, use and approve these documents).
Domain governance makes explicit primary-artefacts, supporting-documents, roles, rules, processes, phases and life-cycles.
Domain governance specifies dependencies with other domains governance practices established in the enterprise.
2 EXAMPLE TW
2.1 Context for Technology Watch function
A typical IT Department uses hundreds digital technologies, tools, products and services from third-party companies to provide highly efficient digital business solutions. There are complex dynamic dependencies between those technologies, tools, products, services, companies and digital business solutions. For example, companies may merge or go bankrupt, products may be discontinued, tools may be exposed to security bridges, new technology may make an existing technology obsolete, etc. All of these may have a negative impact on some digital business solutions or, on the contrary, create an opportunity for improving some digital business solutions.
2.2 Technology Watch (TW) vision and mission
TW vision – timely provisioning IT industry information for decisions related to strategic, tactical and operational aspects of digital business solutions.
TW mission – systematic capturing, analysing, disseminating and exploiting information about used digital technologies, tools, products and services.
2.3 TW governance
TW function operates with three primary-artefacts:
Critical Watch Artefact (CWA) – a technology, tool, product, service, company to be watched
TW-Event (TWE) – a fact of detecting something interesting about a particular CWA
TW-Decision (TWD) – a decision taken for a particular TWT
The relationships between these primary-artefacts is depicted in figure BELOW. Monitoring of a CWA may detect hat something of interest has happened with this CWA and thus to trigger the initial analysis. The latter may lead to a deeper investigation and a decision for dispatching some ITSM processes.
Figure 1
3EXAMPLE SOA Governance
3.1 SOA Governance vision and mission
SOA vision – considerably speed-up the delivery and evolution of software-intensive digital business solutions.
SOA mission – industrialise the delivery of software-intensive business solutions as a set of autonomous components (i.e. services).
3.2 SOA Governance approach
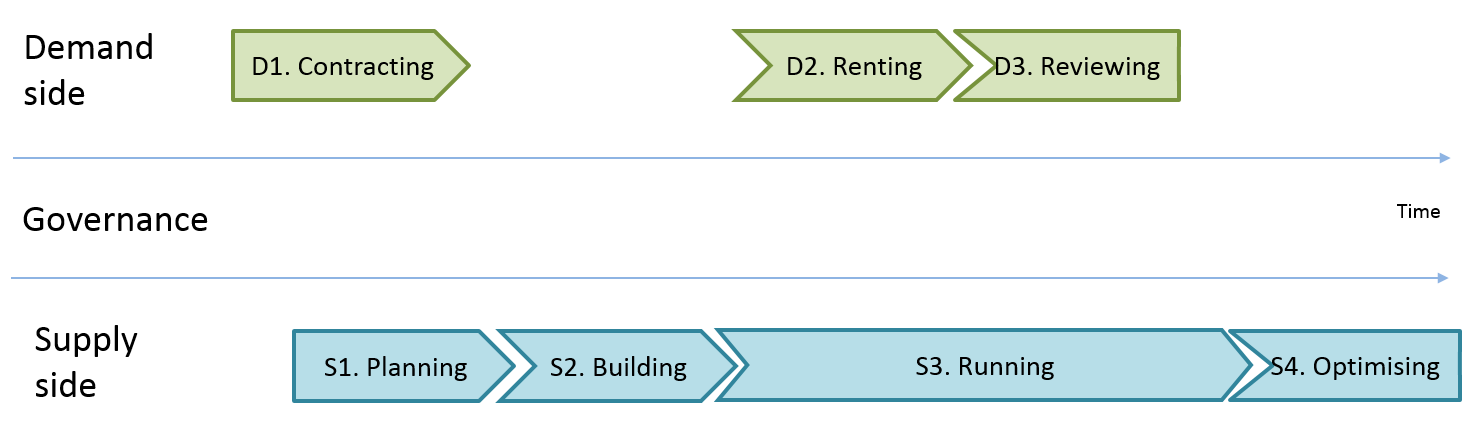
SOA governance is balancing the demand side and supply side. Some service providers (supply side) may be temporary not consumed. Some service consumers (demand side) may use the same service provider. A service consumer (demand side) may use a few service providers at the same time.
Figure 2 Links between service consumers and service provides
The life-cycle of service demand comprises the following phases: D1. Contracting, D2. Renting and D3. Reviewing.
The life-cycle of service supply comprises the following phases: S1. Planning, S2. Building, S3. Running and S4. Optimising.
3.3 Scenarios for service provisioning
There are three scenarios in the service provisioning.
1. Scenario “sur mesures” or “make-engineer-to-order” - design a new service and deploy; coordination between phases in this scenario is shown in figure below.
Figure 3 Scenario “sur mesures” for service provisioning
2. Scenario “adaptation” or “make-build-to-order“ - tailor an existing service and deploy; coordination between phases in this scenario is shown in figure below.
Figure 4 Scenario “adaptation” for service provisioning
3. Scenario “prêt-à-porter” or “make-build-to-catalogue” - build some services before actual demands; coordination between phases in this scenario is shown in figure below.
Figure 5 Scenario “prêt-à-porter” for service provisioning
3.4 Stakeholders and their participation into the service demand and service supply life-cycles
Demand side roles are:
demand initiator, e.g. a Head of Department
service consumer, e.g. staff member from a Department
Supply side roles are:
service owner, e.g. somebody from the IT department
service implementer, e.g. a preferable partner
service operator, e.g. a preferable partner or the IT Department (actually, its OPS group)
Governance side role is:
service auditor, e.g. somebody from the IT department, EA function or third-party
General participation of various roles in all phases is depicted in figure below (the first pattern for service provisioning is used).
Figure 6 Participation of some roles
The detailed participation of various stakeholders is shown below in accordance with the RACI technique.
service
demand
service
supply
contracting
renting
reviewing
planning
building
running
optimising
Demand initiator
(demand side)
RA
RA
R
C
I
I
C
Service owner
(supply side)
C
C
C
RA
C
I
R
Service implementer
(supply side)
C
-
-
-
RA
C
C
Service operator
(supply side)
C
C
I
-
C
RA
C
Service consumer
(demand side)
C
I
C
-
C
I
C
Service auditor
(governance side)
I
I
A
I
-
I
A
3.5 Outline of the process
The coordination between the two life-cycles is shown in figure below. The pink numbered markers show the sequence in the control flow (only the “happy” path). The solid arrows are used within each of the life-cycles. The dashed arrows are used between the two life-cycles.
Figure 7 Coordination between two life-cycles
This figure is the base for defining the domain documents and their life-cycles as well (thus governing bodies which approve these documents).
Business artefacts are available in digital formats (thus formal and executable).
Digital is the master media for business artefacts.
Enterprise, ecosystem and society “understand” the digital formats for business artefacts (not consider digital artefacts as BLOBs).
Enterprise can transmit, protect, validate, enrich, interpret and manipulate digital business artefacts at their whole life-cycle.
Enterprise can generate new knowledge from digital business artefacts.
Enterprise knows all the dependencies between its digital business artefacts (i.e. how a change in an asset affects some other assets).
Enterprise can transform digital business artefacts (extract, combine, change presentation, convert, etc.) to fit the current needs of a particular customer.
Business artefacts can be moved between digital, analog and physical medias (e.g. with 3D printing).
Enterprise can capture the external physical world into its digital artefacts.
Business digital artefacts may be offered for consumers as apps.
People can delegate to "things" (i.e. computers and robots) some routine activities with their business artefacts (e.g. with the use of #IoT)
With the progress of #IoT, "things" become more capable actors of digital business processes ("things" may form temporary groups to cayy out a particular activity).
Digital business artefacts help increasing flexibility of enterprise systems (from www.samarin.biz/book ):
All artefacts must be versionable throughout their lifecycle
All artefacts must evolve to become digital, externalised, virtual and components of clouds
All relationships between artefacts must be modelled explicitly







 Posts

